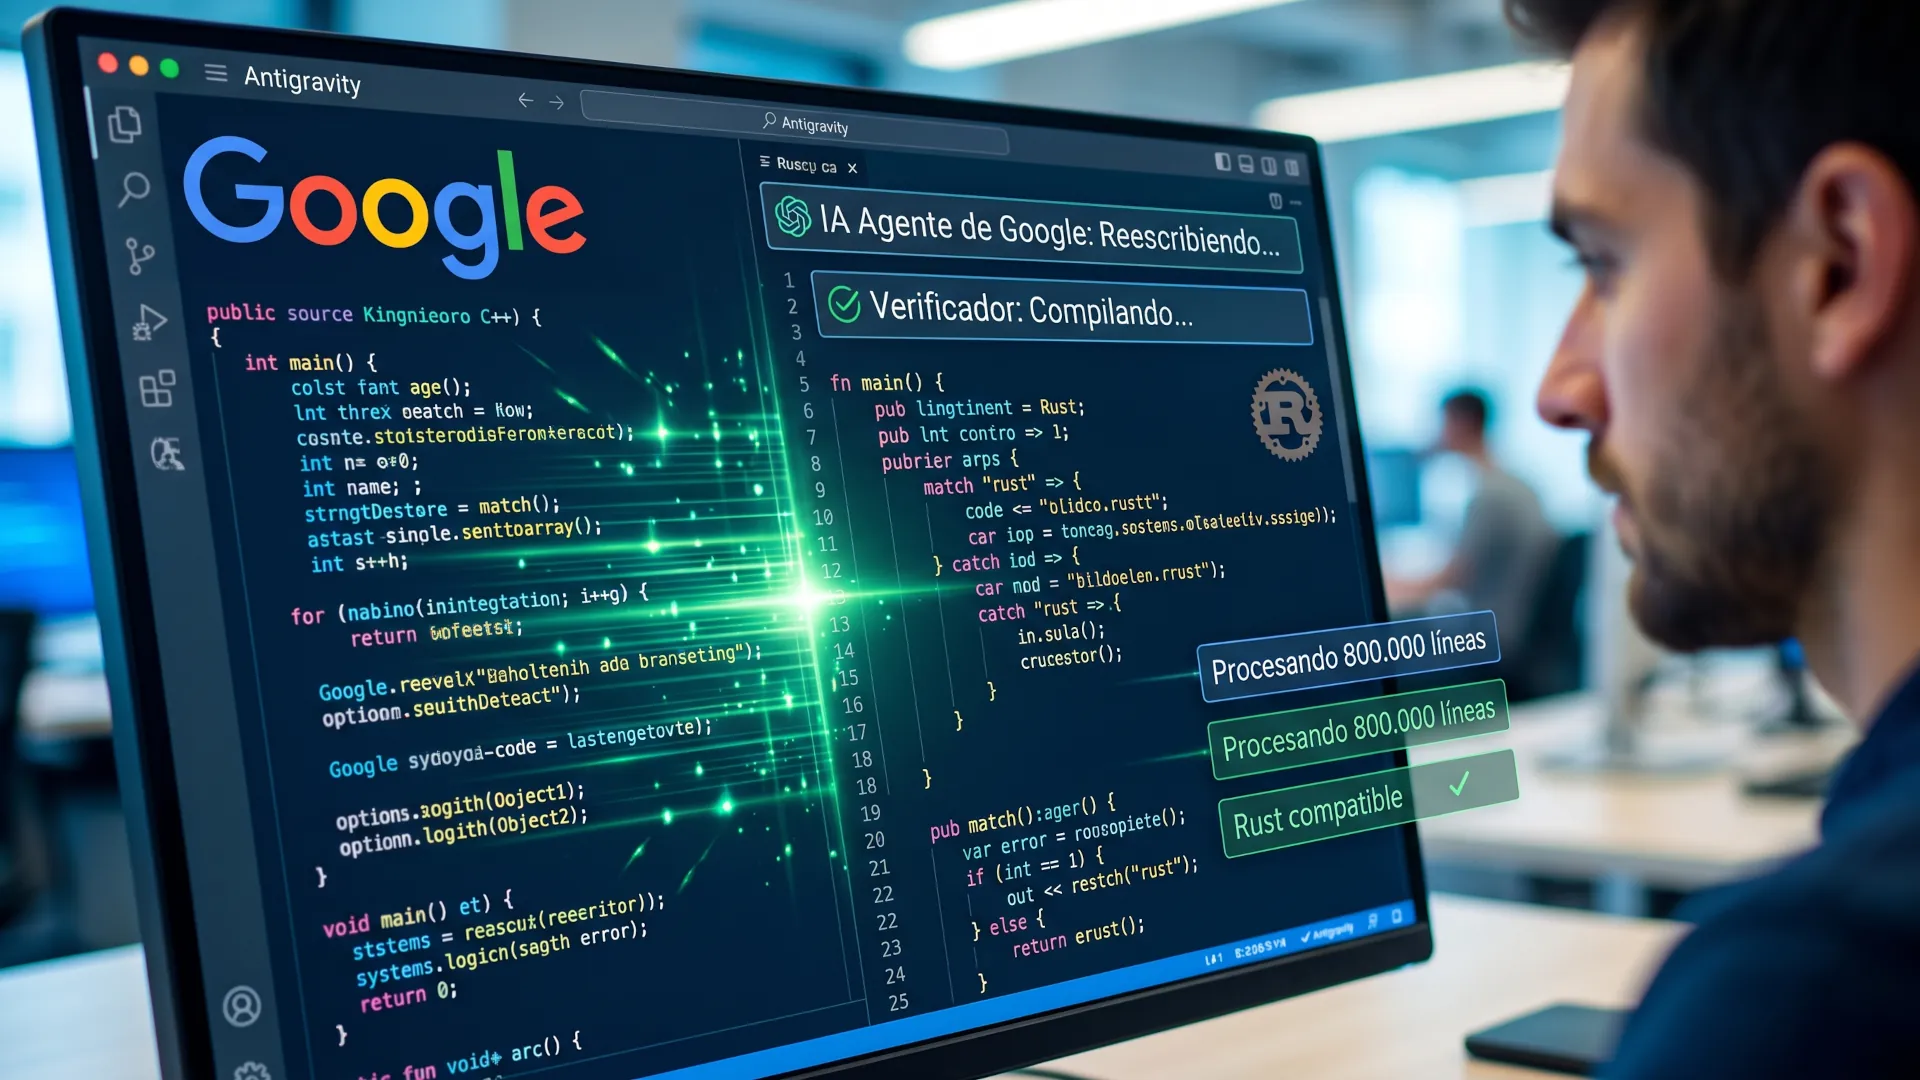
Google says its agents formalized the Weil conjectures in Lean and translated Zircon to Rust: 1.8 million lines and 800,000 lines according to its November 13 post, without independent verification. The key is not the figures, but the verifier that rejects what does not compile.
The result published by Google Research on November 13, 2026 attributes those figures to /teamwork, a multi-agent system built on the Gemini 4 models within its Antigravity programming environment. The centerpiece is not the model, it is the verifier —Lean 4 in math, the original suite in code— which rejects every proposal that does not pass.
That detail changes the conversation about what an agent can do. The problem with models that write code was never generating a plausible solution, it was distinguishing it from one that works. With a verifier in the loop, plausibility stops mattering and the system can afford to explore in parallel, discard and try again. The consequence is that the bottleneck moves: it is no longer in producing candidates, it is in defining what counts as valid proof and who signs off on that definition.
What have they done and with what evidence?
The most striking case is the formalization of the Weil conjectures, a set of results on the number of solutions of polynomial equations over finite fields that Pierre Deligne proved in 1974. The system produced a complete formalization in Lean, some 1.8 million lines, over 28,800 subagent invocations, according to the company's count.
The second block is engineering. Building on a prior port of 25% of the Zircon microkernel, a two-week campaign rewrote the rest of the C++ code into some 800,000 lines of safe Rust, with the claim that it passes the kernel's unit tests and boots on arm64 hardware. In parallel, the libgav1 video decoder was moved to Rust with bit-for-bit parity and ended up between 20% and 30% faster than the original C++ and assembly.
The third leg is verification of the method, not the result. Agents that translate code tend to cheat: they comment out dependencies, rewrite tests or leave gaps so the whole thing compiles. The rewrite pattern Google describes programs each module only when its dependencies compile and links it against the original test suite without modification, which closes the door to that shortcut.
The role of the verifier
The difference between a useful agent and a generator of technical debt lies in who checks. A proof checker like Lean 4 does not accept a doubtful step, and an inherited test suite does not adapt to the taste of whoever is translating. Those two pieces turn the model's work into something an engineer can audit without reading every line.
The limit is just as important. Lean verifies that the proof is correct with respect to a statement, not that that statement is the theorem that was meant to be proved. Translating mathematical intuition into formal language is still human work, and that is where errors slip in that no verifier detects.
That distinction is not an academic detail. A system that formalizes badly translated statements well produces impeccable results on problems nobody posed, and the mathematical literature is full of such cases long before language models existed.
Something similar happens with code. Passing the kernel tests shows that the code does what the tests expect, and the tests are only as good as whoever wrote them. A port that boots and passes the suite can still have a concurrency problem that nobody tested, and the departure of reviewers from the Linux kernel reminds us that in that project human review is not an ornament.
The Rust rewrite stops being an experiment
For years, moving code to Rust was a statement of intent: memory safety in exchange for rewriting half a product. What changes with this kind of campaign is the economics of the process. If a team can translate 800,000 lines in two weeks and validate them against existing tests, the debate stops being whether it is worth it and becomes what gets translated first.
The closest precedent in the world of consumer software is Discord's abandonment of Electron, where the figure that mattered was not speed, but memory: 290 megabytes versus the usual gigabyte. In the kernel the criterion is different, because memory safety is not an optimization, it is the difference between a crash and a privilege escalation.
It is worth maintaining skepticism. Google does not publish cost, wall-clock time, or how many of its campaigns failed. Nor is there independent review of the mathematical results, and another formalization of Weil had appeared days earlier by another route. A lab announcement with public repositories is partly verifiable, not entirely.
800,000 lines: what is proven and what is not
The first problem is maintenance. Code generated and validated against tests is a starting point, not a product. Someone has to understand why that module is written that way when the first production failure arrives, and that someone cannot be the model that no longer remembers the campaign.
There a tension appears that anyone who has inherited someone else's code knows well: the faster it is produced, the more expensive it is to maintain. Generation speed does not change the nature of the subsequent work, it only shifts it to a team that did not take part in the decision.
The second is review. If the bottleneck of open source is reading other people's code, a system that produces eight hundred thousand lines makes it worse before it makes it better. The only way for the math to work out is for the verifier to also act as reviewer, and that only covers what can be checked mechanically.
The third is the distribution of credit. A result that mixes human researchers, agent patterns and automatic checkers breaks the categories by which academic work is measured. Universities are already discussing how to cite a contribution made with these tools, and the problem is no small matter when the result ends up in a proof library that others will use.
AI, software development and the future
The first signal will be the failure rate. When a lab publishes successes and does not count failed attempts, the productivity figure is incomplete. The second will be the cost per result, because a two-week campaign with tens of thousands of invocations is not free even if the code is.
The third affects those who program. If these tools reach small teams with the same verification pattern, the competitive advantage will stop being in writing code and shift to defining what counts as correct. That already happens in formal mathematics, where the bottleneck is stating things well.
The honest summary is that the news is not that a model writes Rust, it is that the method includes a mechanism that can tell it no. Everything else, including the spectacular figures, depends on that mechanism being well designed.